

New Characters Exploit Lookalike Domains to Bypass Browser Security
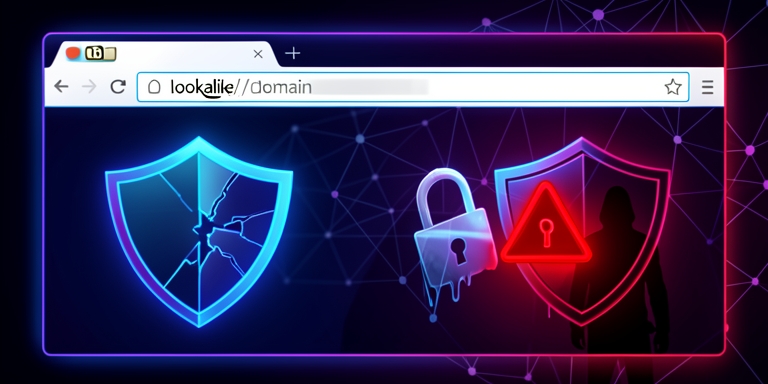
Researchers from Have I Been Squatted identified that specific Unicode characters can mimic standard Latin letters in Chromium-based browsers, creating deceptive domains.
Researchers and Findings
Researchers from Have I Been Squatted identified that specific Unicode characters, including the Cyrillic ‘ө’ and Latin ‘ƙ’, can mimic standard Latin letters such as ‘e’, ‘o’, and ‘k’ in Chromium-based browsers. These visually similar characters exploit browser rendering mechanisms to create domains that appear legitimate but are designed to deceive users.
Vulnerabilities in Domain Validation
The findings highlight vulnerabilities in domain validation systems that fail to distinguish between homoglyphs and standard alphanumeric characters. Attackers could leverage this flaw to establish phishing sites, malware distribution channels, or other malicious infrastructure under the guise of trusted entities.
Discovery and Technical Analysis
The discovery underscores the need for enhanced domain name system (DNS) filtering and browser-level safeguards against homograph attacks. Technical analysis revealed that the affected characters are not flagged by current internationalized domain name (IDN) processing rules, allowing them to bypass existing security protocols.
Recommendations for Security Professionals
Security professionals are advised to monitor for unusual domain patterns and implement additional verification layers for high-risk environments.
According to the research, the use of homoglyphs in domains poses a significant risk to user security, emphasizing the importance of updated DNS and browser safeguards.
About Author

 English