

AI Red Teaming vs Traditional App Security Testing
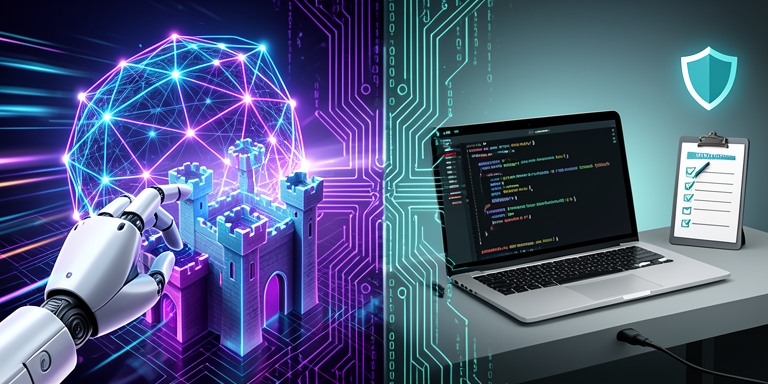
AI applications necessitate a distinct approach to security testing compared to conventional web applications and APIs.
AI Red Teamings versus traditional Application Security testing
Traditional penetration testing focuses on network protocols, authentication mechanisms, and data processing logic. In contrast, AI red teaming targets vulnerabilities specific to machine learning systems such as prompt injection, model extraction, and training data poisoning—threats absent in conventional software architectures (Source: OWASP Top 10 for Large Language Model Applications, owasp.org). This divergence creates a critical testing gap where standard methodologies fail to address the core risks associated with AI systems.
The fundamental shift in attack surfaces
The fundamental shift in attack surfaces when evaluating AI systems involves three primary vectors: manipulation of input prompts (both direct and indirect injection), exploitation of model behavior (including excessive autonomy and data leakage), and vulnerabilities in machine learning supply chains (Source: OWASP Top 10 for Large Language Model Applications, owasp.org). Unlike deterministic applications where identical inputs produce consistent outputs, AI models generate probabilistic responses. This variability complicates reproducible exploit development using traditional techniques.
Testing requirements and expertise
While standard penetration tests examine code and infrastructure, AI red teaming requires access to model weights, training pipelines, or live inference endpoints because model behavior cannot be accurately simulated through configuration alone. A critical question for organizations is whether their security testing includes adversarial prompt construction and model output validation. Without these elements, standard application security testing overlooks the primary attack vectors targeting AI systems.
Key categories of AI-specific threats
The OWASP LLM Top 10 and MITRE ATLAS frameworks identify three key categories of AI-specific threats: prompt-based attacks, model-based attacks, and supply chain vulnerabilities (Source: OWASP Top 10 for Large Language Model Applications, owasp.org; MITRE ATLAS, atlas.mitre.org). Prompt-based attacks exploit the model’s ability to interpret user input versus system instructions. Direct injection attempts to override predefined system prompts through malicious user input, while indirect injection embeds harmful instructions in processed data sources.
Challenges in AI red teaming
Model-based attacks target the inference process and data retention characteristics of AI systems. Techniques such as model extraction aim to reverse-engineer training data or parameters through query patterns, while information disclosure attacks seek to reveal sensitive data from training sets or system prompts. Excessive agency attacks test whether models perform actions outside their intended scope when prompted. These threats demand expertise in transformer architectures, attention mechanisms, and data memorization patterns—domains absent from traditional application security practices.
Supply chain vulnerabilities
Supply chain vulnerabilities involve compromises in the AI development lifecycle. Training data poisoning introduces adversarial examples during model training to create backdoors or biases, while attacks on pre-trained models, training frameworks, or inference infrastructure disrupt system integrity. Validating supply chain security requires access to training pipelines, model provenance records, and deployment artifacts—elements outside the scope of standard penetration testing.
Differences in testing methodologies
Traditional penetration testing follows a linear methodology: reconnaissance, scanning, enumeration, exploitation, and post-exploitation. This approach assumes deterministic outcomes where successful exploitation leads to system access or data extraction. AI red teaming cannot adhere to this model because AI systems lack traditional exploitation points. Instead, success involves manipulating outputs or extracting training data, not gaining administrative privileges.
Reproducibility and probabilistic testing
Automated scanners used in conventional testing cannot detect vulnerabilities arising from model behavior patterns, which exist in training and inference processes rather than deployable code. Many AI vulnerabilities cannot be \\\”patched\\\” through conventional means. A prompt injection flaw reflects limitations in the model’s training rather than a configuration error, requiring retraining or architectural changes. The NIST AI Risk Management Framework (AI RMF) Map 5.2 mandates evaluation of AI system performance under adversarial conditions relevant to their deployment context—requirements unmet by traditional application security methodologies (Source: NIST AI RMF, airc.nist.gov).
Critical risk factors and testing approaches
Reproducibility is another key distinction. Standard penetration tests produce consistent results, while AI model outputs vary between identical requests due to inference sampling and randomness. An adversarial prompt that succeeds in one test may fail in subsequent runs without system changes, necessitating probabilistic testing approaches. Organizations relying on standard methodologies address API security, authentication, and data handling but overlook model-specific threats that constitute the primary risk to AI systems.
Model drift and overfitting
The differences between standard penetration testing and AI red teaming span multiple dimensions. Traditional testing focuses on application code, infrastructure, and defined network boundaries, while AI red teaming examines training pipelines, inference behavior, and the entire AI system lifecycle. Testers control network access, input vectors, and system interactions in conventional assessments, whereas AI red teaming involves prompt construction, model queries, and training data influence when applicable. Two critical risk factors in AI systems—model drift and overfitting—require specialized attention.
Model Context Protocol (MCP) and integration risks
Model drift occurs when deployed systems deviate from their original performance baseline due to changing input distributions, potentially undermining safety training and content filtering. Red team testing must establish behavioral baselines at deployment and conduct periodic adversarial re-testing to detect degradation as operational contexts evolve. Overfitting poses a different risk, as models that memorize training data rather than learning general patterns become vulnerable to training data extraction attacks. Red teams should employ techniques like model inversion and membership inference to assess whether sensitive information can be reconstructed from model outputs.
Testing requirements for MCP
The Model Context Protocol (MCP) introduces new attack surfaces for AI systems. As organizations adopt MCP-compatible architectures to enable AI access to external tools and data sources, red teams must evaluate risks associated with compromised tool definitions, data exfiltration, and unintended system actions. Indirect prompt injection attacks are particularly relevant, as malicious instructions embedded in MCP-connected data sources can alter model behavior during inference sessions. Testing requirements include assessing whether adversarial prompts trigger unauthorized tool usage, whether malicious content from MCP sources influences model outputs, and whether authorization boundaries are enforced when accessing resources through MCP integrations.
Scoping AI red team engagements
Scoping AI red team engagements requires defining three system boundaries: the model inference boundary, training pipeline boundary, and integration boundary. The inference boundary determines what the model can access during operation, including context windows and external data sources. Red teams test whether adversarial prompts can cause the model to exceed its intended scope. The training pipeline boundary encompasses data sources, preprocessing steps, and training infrastructure, with testing focused on detecting data contamination or backdoor injection. The integration boundary involves connections to other applications, APIs, and data flows, requiring analysis of prompt flow and context injection patterns.
Key prerequisites and test objectives
Key prerequisites for AI red teaming include access to model architecture documentation, inference endpoints, training data lineage, integration mappings, system prompt configurations, and behavioral baseline records. Test objectives should address prompt injection resistance, information disclosure risks, excessive agency scenarios, training data extraction vulnerabilities, supply chain integrity, output validation bypasses, cross-system impacts, MCP integration risks, and behavioral drift assessments. Organizations must prioritize high-risk model interactions when defining engagement scopes, focusing on scenarios where manipulation could lead to business impacts or data exposure.
This content was reviewed and approved by a cybersecurity practitioner participating in CyberRisk Alliance’s Expert Review Program. Reviewers assess technical accuracy, relevance, and alignment with current industry practices. Senior technology leader with 15+ years of experience delivering large-scale digital transformation, real-time embedded systems, global programs, and operational excellence across industrial, defense, healthcare, telecommunications, and enterprise sectors. Proven ability to lead distributed teams, manage multimillion-dollar initiatives, and drive measurable business outcomes including revenue growth, cost optimization, and accelerated time-to-market. Expert at bridging business and technology—leading strategy, client engagement, and execution. Experienced in global delivery models, Agile transformation, and stakeholder alignment.

About Author

 English